78.69% fewer evidence losses than screenshots
A required value can sit outside the captured viewport. A list can end past the last frame. A control's state can be hard to read from pixels. In each case a screenshot verifier works from partial evidence. On the same runs and the same frozen rubrics, W8's DOM-diff Optimized record kept the required evidence far more often.
| Recorded run | Tasks | Criteria | Screenshot losses | W8 DOM losses |
|---|---|---|---|---|
| run_1 | 97 | 619 | 51 (8.24%) | 16 (2.58%) |
| run_2 | 97 | 619 | 62 (10.02%) | 15 (2.42%) |
| run_3 | 97 | 619 | 70 (11.31%) | 8 (1.29%) |
| Mean per run | 97 | 619 | 61.00 (9.85%) | 13.00 (2.10%) |
| Listed access-blocked tasks excluded, mean | 88 | 572 | 60.00 (10.49%) | 11.00 (1.92%) |
Paired difference: 7.75 points (95% interval 4.07–11.71). Relative reduction from the mean counts: (61 − 13) / 61 = 78.69% (57.25–91.62%).
Where evidence disappeared
Each confirmed loss gets one primary type. The counts below are means per run on the matched panel, so they can be fractions. Across the three runs the audits flag 219 run-and-criterion observations, covering 118 distinct criteria across 49 tasks.
| Loss type | Screenshot | W8 DOM |
|---|---|---|
| Exact text and values | 25.00 | 5.67 |
| URLs | 0.33 | 1.00 |
| Control states | 0.67 | 0.67 |
| Table entries | 19.00 | 0.00 |
| Label–value links | 3.33 | 4.00 |
| Capture omissions | 12.67 | 1.67 |
| All types | 61.00 | 13.00 |
The URL row is small on both sides because of the audit rule. The task's start URL and the executed action history are shared inputs, credited to both records. An absent address bar alone is no loss. A page field that holds a URL still counts, and that is where the W8 side loses one.
Five findings from the saved audits
Each one links to the saved audit record in the published dataset. The first is reproduced from the recordings themselves.
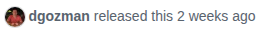
- run_1, task_08, C2, publication date. The W8 record holds “dgozman released this 14 Oct 11:51”, and the releases list one step earlier holds “v1.64.1 Latest Oct 14, 2026”. The screenshots show “released this 2 weeks ago”. Audit · Screenshot run · W8 run
- run_1, task_35, C2 to C4, a cropped row. The W8 record holds the Linux/amd64 size row for the third Docker tag. The screenshots crop that row. One capture gap, three affected criteria. Audit
- task_37, C4, all three runs, a loss on each side. The W8 record keeps availability checkmarks where the screenshots show hollow boxes. The screenshots keep “Golden Gate” capitalized where the W8 record lowercases it. Each side loses a different required item. Audit
- run_1, task_02, C2, a label without its value. The screenshot links “Published by” to “Microsoft Studios”. The W8 record drops that link. A W8 loss. Audit
- run_1, task_48, C0, a checked box. The screenshots show the Accounts checkbox checked. The W8 record lists the control without its state. A W8 loss. Audit
The full criterion table, with citations into the saved audits
Verifier misses are a separate count
Fewer source losses do not mean fewer grader mistakes. On the matched panel the audits flag 54.67 screenshot verifier misses per run (8.83%) and 63.33 DOM verifier misses (10.23%). A miss is available evidence that a verifier overlooked or misread. The two counts measure different things: what the record kept, and what the grader did with it. Neither is a verifier accuracy score. That would need independent correctness labels.
Same run. Same rubric. Different evidence.
- Record three times. The acting model, gpt-5.6, works from W8's DOM text and executable references. Each task runs three times. Each run yields a list of actions and the browser states between them, with a screenshot at each state.
- Keep both views. Screenshots and DOM-diff Optimized come from the same run, aligned by action step.
- Freeze the rubric. Both verifiers get the same task, action history, final answer, frozen rubric, and scoring controls. One frozen rubric serves all three runs of a task.
- Score both. A screenshot verifier and a DOM verifier judge the same criteria from their own evidence.
- Audit the sources. One model inventories the evidence for each criterion. A second model adjudicates. WootzApp staff review the findings.
- Count one-sided gaps, then average. A criterion counts against a record only when the evidence is missing there and present in the other. Counts are averaged over the three runs on the matched panel.
| Role | Model or reviewer |
|---|---|
| Browser-action generation, from DOM text | gpt-5.6 |
| Rubric generation and evidence judging, both verifiers | gpt-5.2 |
| Action and validity judging, both verifiers | gpt-5.6-terra |
| Evidence inventory | gpt-5.6-sol |
| Adjudication | gemini-3.1-pro-preview |
| Internal review | WootzApp employees |
Read the exact metric definition
The metric covers one-sided evidence loss. It does not cover evidence missing from both records. Agent success, answer correctness, verifier accuracy, and training gains are measured apart.
The intervals resample tasks, then runs within tasks, with the audit labels held fixed. They do not cover annotation error. The findings are model-generated, with internal review as a separate role. The matched panel covers 97 of the 100 tasks. Three tasks have a run with no captured state; they stay out of the panel and are never counted as zero loss. The access-blocker subset was defined after the recordings were inspected and is exploratory.
Smaller representation, richer context
The model-facing W8 record of one captured state averages 5.25 KiB across the 2,592 states in all 300 retained recordings. The paper sets it beside the two denser forms W8 keeps for each state.
| Record | File | Mean size per state |
|---|---|---|
| DOM-diff Optimized | dom_model.txt, compact model-facing text | 5.25 KiB |
| Text-dense DOM | dom_full.txt, detailed readable text | 47.26 KiB |
| Full DOM | dom.json, structured snapshot | 206.45 KiB |
This compares stored size per state. Evidence kept, task success, token use, verifier cost, and training time are measured apart.
A better reward starts with a better record
A model judge cannot recover a value that was never saved. A deterministic checker needs the relevant state captured in the first place.
W8's record cuts missing browser evidence by a measured amount. The audit shows where DOM text falls short too: label–value links, control states, and some exact values. The next step is to turn the preserved evidence into task-specific checks for state and outcome changes. Screenshots and human or model judgment stay where visual criteria demand them.
| Step | Status |
|---|---|
| Evidence capture | Measured on three runs, 619 criteria each |
| Renderer and policy ablations | Future work in the paper |
| Criterion checks | Next engineering step |
| Trusted rewards | Next engineering step |
| Evaluations and training | Next engineering step |
Inspect the evidence. Reproduce the result.
- Paper: method, results, and appendices
- Technical report: pipeline, equations, and the criterion table
- Results index, summary.json, and the category table
- The six loss types
- Recorded-run aggregator: recompute the means offline, no model calls
- Saved evaluations: frozen rubrics, verifier results, and audits
- Browser Agent Tasks dataset
- Openrind Shell OpenShell runtime source
Bring a workflow where your traces or screenshots fail to explain what happened. We will compare the evidence the harness emits with what the runtime and the browser can keep. Discuss a benchmark run.